william

Keep Calm and Markdown.

docker buildx: the builder had a proxy, the client didn't

My image build script started failing on its very first line, FROM python:3.10, with failed to fetch anonymous token ... TLS handshake timeout. The odd part: the buildx builder I use is created with a proxy for exactly this reason, and from another shell the same build worked.

The token request is not made by the builder. It is made by the docker buildx client in your own shell, using your shell’s proxy variables. My interactive zsh exports none, so that one request went direct and timed out. Two export lines in the build script fixed it.
Logging a full pandas DataFrame from an f-string: rebuild it from the caller's source

A daily script of mine logs its intermediate DataFrames with log.crt(f"""...{tgt = }..."""). The log showed 10 of the 90 rows, with the header stuck to the end of tgt = . Switching to tgt.to_string() printed every row, but the header ended up two columns left of the data.

The fix I ended up with keeps the f-string as it is and adds one argument: log.crt(f"...{tgt = }...", full=True). That looks impossible, because the f-string is already built when the logger runs. The logger gets around it by finding the f-string in the caller’s source and evaluating it a second time.

Fixing duplicated tmux status bars and missing icons in Termius on iPhone

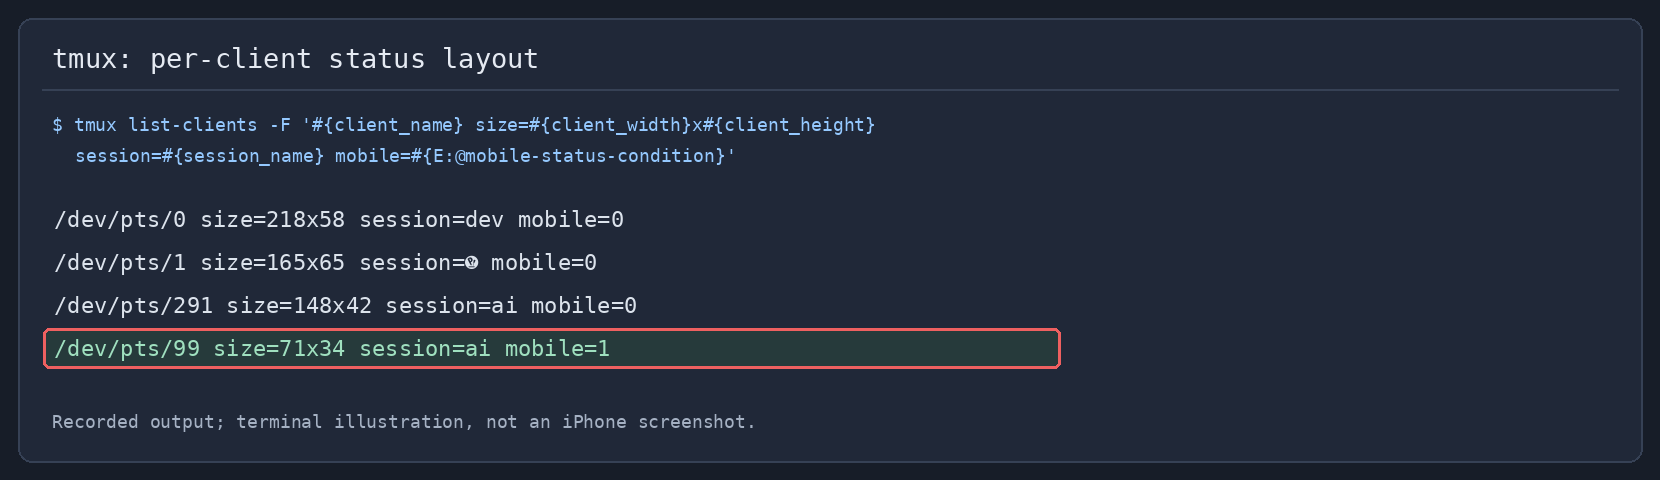
My tmux status bar looked fine on Linux, but connecting to the same session from Termius on my iPhone left repeated copies of the bar at the bottom of the screen. Moving it to the top was a useful workaround. I wanted to keep it at the bottom and keep the desktop’s colors and useful widgets.

The fix was a compact renderer for clients below 100 columns, followed by a targeted replacement for an icon the phone could not render. This extends my one-job status renderer: the phone still uses one status job, and a desktop attached to the same session keeps its full layout. The app is Termius, although I initially called it Terminus.

Profiling Neovim startup: lazy-loaded plugins that weren't lazy

Update 2026-10-17: the next pass looked at big log files, and found an nc mapping that made every n wait timeoutlen (500 ms) in every file. See Profiling Neovim on big logs.

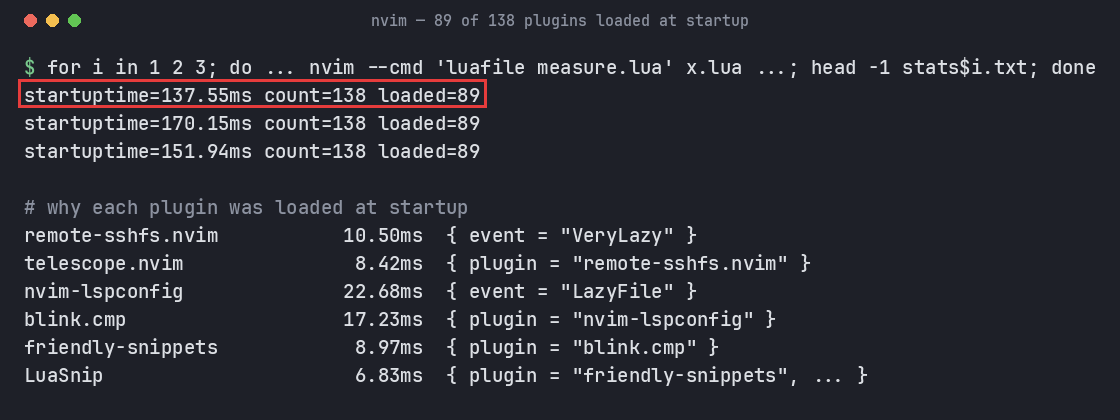
After tmux and zsh, I looked at Neovim. My config has grown to 138 plugins on lazy.nvim and LazyVim. Almost every spec has an event, cmd or keys, so I assumed most of them were lazy. They weren’t: 89 of the 138 plugins loaded at startup.

None of the causes was a slow plugin. They were config mistakes that only show up once you ask lazy.nvim why each plugin loaded. I fixed them in two rounds:

before after
CPU time to first screen, opening a new file ~150 ms ~120 ms
CPU time to first screen, no file (dashboard) 69 ms 50 ms
plugins loaded at startup 89 73

Profiling zsh: a Python plugin was adding 190 ms to every command

After fixing tmux, I looked at the shell running inside it. My zsh config had grown over a few years to about 30 plugins and Oh My Zsh snippets on top of zinit and Powerlevel10k. It felt a little heavy, but nothing stood out.

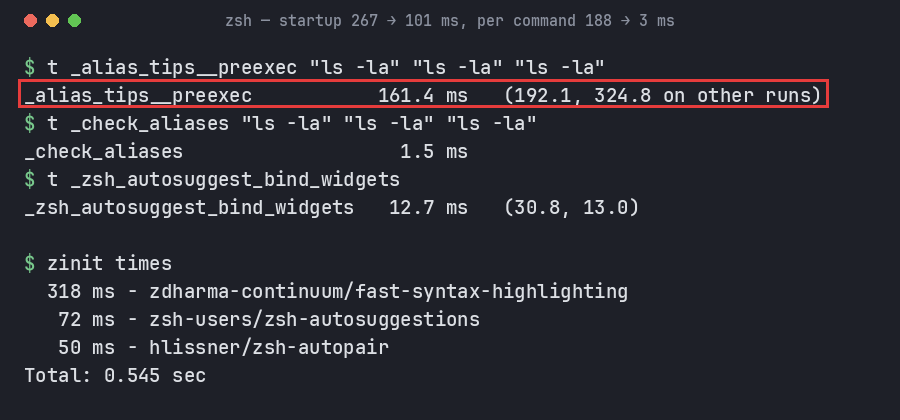
Measured properly, it was slow in three separate ways, each with its own cause:

before after
startup to a usable shell 267 ms 101 ms
added to every command 188 ms 3 ms
added to every prompt 15 ms 4 ms

This post covers how I measured each one, the fixes, and how I checked that the fixes didn’t change anything else. That check caught two mistakes of my own.

A Claude Code skill and subagent that write posts for this blog

Most of my recent posts start the same way: I debug something in a Claude Code session, then ask it to “write this up”. Without guidance the result is generic: wrong front matter, a made-up category, marketing intros, and sometimes output that was never actually printed. So I gave the repo two small files that teach Claude Code how this blog works: a skill (blog-post) and a subagent (blog-writer). This post is how they are set up. It was written with the skill.

0%